🚀 SpaceXAI Releases Grok 4.7: Built for Long-Running Coding and Knowledge Work
✨ A bigger base model and longer training on hard, multi-hour tasks, at the same price as Grok 4.6.
🌐 Introduction
SpaceXAI today released Grok 4.7, which it calls its most capable model for coding and knowledge work. According to the announcement, the model works longer on difficult tasks, checks its own work more carefully and ships with SpaceXAI's best-calibrated safeguards so far.
The headline pitch is about cost as much as capability:
💡 "Twice as fast, at half the price of comparable models."
— SpaceXAI, Grok 4.7 announcement
Grok 4.7 is available today in Cursor and Grok Build, through the Grok API, and via third-party coding harnesses, model routers and cloud platforms.
🧠 What Changed Under the Hood
SpaceXAI describes three main changes from Grok 4.6:
| Change | What SpaceXAI says |
|---|---|
| 🏗️ Bigger base model | Grok 4.7 is built on a new, larger base model than Grok 4.6 |
| 🔄 Longer RL run | A longer reinforcement learning run on a harder mix of tasks, weighted toward problems that take many hours to complete |
| 🤖 Native Grok Bot harness | The model was trained to natively understand the Grok Bot harness, the agent environment behind SpaceXAI's always-on AI teammates |
Press coverage, including TechBriefly, sums up the release as a larger model at the same price. SpaceXAI says it is "served at the same price and speed as Grok 4.6."
📊 Benchmarks
Here are the scores SpaceXAI published. These are vendor-reported results and haven't been independently reproduced yet.
| Benchmark | Grok 4.7 | Grok 4.6 | GPT-5.6 Sol | Fable 5.1 |
|---|---|---|---|---|
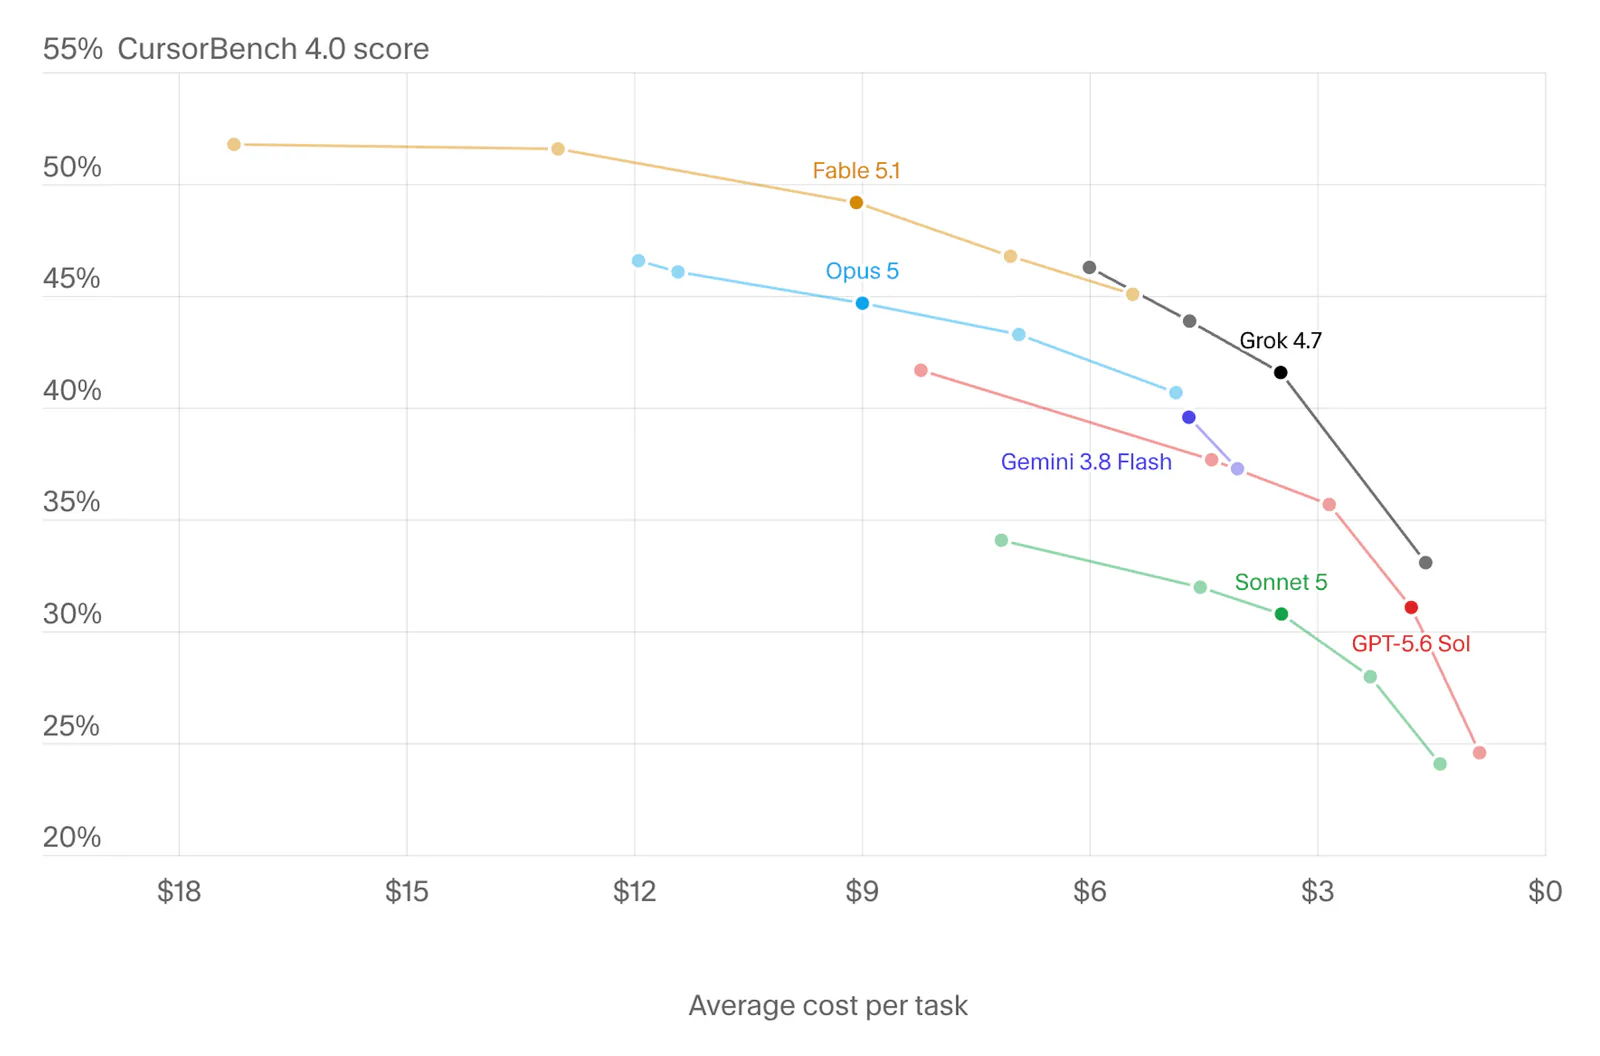
| CursorBench 4.0 | 46.3% | 40.4% | 41.7% | 51.8% |
| DeepSWE v1.1 | 71.0%* | 65.2% | 72.7% | 70.0% |
| EEBench | 64.0% | 53.0% | 39.4% | 56.4% |
| AA Briefcase v1.1 | 1,657 | 1,546 | 1,487 | 1,678 |
| Terminal-Bench 4.0 | 37.6% | 20.3% | 37.3% | 57.9% |
| Harvey Legal Agent Benchmark | 19.6% | 15.8% | 2.5% | 6.7% |
| HealthBench Professional | 56.7% | 48.5% | 60.5% | 62.1% |
*High-effort score.
CursorBench 4.0 score vs average cost per task, as shared at launch. Source: Cursor
🔍 How to read these numbers
- The biggest jump is in terminal work. Terminal-Bench 4.0 nearly doubles, from 20.3% to 37.6%, which puts Grok 4.7 roughly level with GPT-5.6 Sol.
- Specialist knowledge work improves a lot. Grok 4.7 leads this comparison on EEBench (electrical engineering) and on the Harvey Legal Agent Benchmark.
- It doesn't lead everywhere. Fable 5.1 scores higher on CursorBench 4.0, Terminal-Bench 4.0, AA Briefcase and HealthBench Professional. GPT-5.6 Sol scores higher on DeepSWE and HealthBench Professional.
- Price-performance is the main argument. SiliconANGLE reports that Grok 4.7 completed CursorBench 4.0 tasks at an average cost of $4.69 per task, which it says beats GPT-5.6 Sol and Fable 5.1.
💰 Pricing and Specs
The standard price is unchanged from Grok 4.6:
| Item | Grok 4.7 |
|---|---|
| 🆔 API model ID | grok-4.7 |
| 📏 Context window | 500,000 tokens |
| 📅 Knowledge cutoff | May 2026 |
| 💵 Input | $2.00 per million tokens (prompts under 200K) |
| 💾 Cached input | $0.50 per million tokens (prompts under 200K) |
| 📤 Output | $6.00 per million tokens (prompts under 200K) |
| 📚 Long prompts (200K and up) | $4.00 input / $1.00 cached / $12.00 output per million tokens |
| ⚡ Fast variant | Twice the output speed at twice the price |
The context window and knowledge cutoff come from SpaceXAI's developer docs, not the launch post. DataCamp also noted that the 500K figure was missing from the announcement itself.
🛡️ Safety
SpaceXAI says Grok 4.7 runs on an entirely new safeguard stack and is "the strongest model we've tested on refusals and jailbreak resistance."
Published safety results:
- 🧬 62.4% on LatchBio's biosafety benchmark
- 🔐 Only 3.3% of risky dual-use prompts allowed through on HackerBench v0.3
- ✅ SpaceXAI says legitimate security work is rarely rejected
🛠️ What It Means for Teams and Developers
For a software consultancy, Grok 4.7 is less about a new top score and more about cost per finished task. Here is how we see it.
✅ Where to try it first
| Use case | Why Grok 4.7 fits |
|---|---|
| 🖥️ Agentic coding in Cursor | Available on day one, with clear gains on CursorBench and Terminal-Bench |
| ⏱️ Long-running agent jobs | Training focused on multi-hour tasks, and the model understands the Grok Bot harness natively |
| 📑 Long-document and repo work | A 500K-token context window. Prices double above 200K tokens, so plan for that |
| ⚖️ Specialist domains | Strong vendor-reported results on legal (Harvey) and electrical engineering (EEBench) tasks |
⚠️ What to check
- Benchmark on your own work. The published numbers are SpaceXAI's own. Run Grok 4.7 next to your current model on real tickets from your backlog before you switch.
- Watch the 200K pricing threshold. Above 200K tokens, input and output prices double. Agents that keep reloading a large repository can cross that line without anyone noticing.
- Choose standard or fast on purpose. The fast variant costs twice as much. Use it for interactive work where latency matters, and the standard variant for background jobs.
- Keep fallbacks. Cursor's announcement says Grok 4.6 is still available and that Composer remains its fast, cost-efficient model for everyday coding. Routing by task type is still the sensible approach.
Our recommendation:
- ✅ Pilot Grok 4.7 on one long-running engineering workflow
- ✅ Track cost per completed task, not just cost per token
- ✅ Keep humans reviewing changes the agent produces until you have your own reliability data
✨ Conclusion
Grok 4.7 is an incremental release, but a meaningful one. It brings a larger base model, longer training on hard multi-hour work, native support for the Grok Bot harness and a rebuilt safety stack, all at Grok 4.6 prices. It doesn't win every benchmark: rivals still lead on several coding and health evaluations. But the jump in terminal work and the price-performance argument make it worth a serious trial for any team running agentic coding or knowledge-work pipelines.
💭 Frontier models are now competing less on peak scores and more on how cheaply they can finish long, hard jobs.
Tags: #Grok47 #SpaceXAI #LLM #AICoding #AgenticAI #AIModels
Sources:
- Introducing Grok 4.7 — SpaceXAI
- Grok Models & Pricing — SpaceXAI docs
- Introducing Grok 4.7 — Cursor blog
- Grok 4.7 is now Live! — Cursor Community Forum
- SpaceX launches Grok 4.7 with long-horizon processing, safety upgrades — SiliconANGLE
- Grok 4.7: Features, Benchmarks, and Pricing — DataCamp
- SpaceXAI gives Grok 4.7 a larger base model at the same price — TechBriefly
Media credits:
- Hero image and CursorBench 4.0 chart — Cursor