⚡ Claude Sonnet 5.5: Opus-Class Coding at Sonnet Prices
✨ Anthropic's mid-tier model is faster than Sonnet 5, costs less per task and, on one key agentic coding benchmark, scores higher than Opus 5.5.
🌐 Introduction
Anthropic today released Claude Sonnet 5.5, the second model in the Claude 5.5 family. It follows Claude Opus 5.5, which launched six days ago. Anthropic calls it "a clear upgrade over Claude Sonnet 5". The company says it runs 30%+ faster and costs up to 30% less for most work.
The price per token has not changed. The model is available today on the Claude Platform as claude-sonnet-5-5, and on Amazon Web Services, Google Cloud and Microsoft Azure.
💡 Anthropic says Sonnet 5.5 is "our fastest Sonnet model to date."
💰 Pricing: Same Rate Card, Lower Bills
| Price per 1M tokens | Claude Sonnet 5.5 |
|---|---|
| 📥 Input | $2 |
| 📤 Output | $10 |
| ⚡ Cache reads | $0.20 |
| 🗂️ Cache writes | $2.50 |
Input and output prices are the same as Sonnet 5. The savings come from efficiency: Anthropic says that in its testing, Sonnet 5.5 "costs up to 30% less per task than its predecessor." It also generates output 30%+ faster.
Opus 5.5 costs $4/$20 per million tokens, so Sonnet 5.5 is half the per-token price of Anthropic's flagship.
📊 Benchmarks: A Big Jump in Agentic Coding
The standout number is Terminal-Bench 4.0, an agentic coding test of complex, multi-step work in a command-line environment. Sonnet 5.5 scores 70.6%. Sonnet 5 scored 10.3%, and Opus 5.5 scored 66.4%. Anthropic notes that the Opus 5.5 figure is its result at Xhigh effort, which is that model's highest score.
| Benchmark | Sonnet 5.5 | Sonnet 5 | Opus 5.5 |
|---|---|---|---|
| 💻 Terminal-Bench 4.0 | 70.6% | 10.3% | 66.4% |
| 🖱️ CursorBench 4.0 | 55.5% | 34.1% | 57.8% |
| 🧪 FrontierCode 1.1 (Main) | 46.2% | 42.4% | 54.4% |
| 📚 GDPval-AA v2.1 (knowledge work) | 1844 | 1449 | 1846 |
| 💼 AA-Briefcase v1.1 | 1811 | 1359 | 1822 |
| 🧠 Humanity's Last Exam (with tools) | 64.5% | 54.9% | 67.7% |
| 🖥️ OSWorld 2.1 (computer use, partial) | 80.1% | 57.0% | 81.8% |
Sonnet 5.5 beats Opus 5.5 on Terminal-Bench. On most other rows it stays close to Opus, and on FrontierCode and Humanity's Last Exam the gap is wider. Anthropic also says that at Medium effort, the default in the Claude apps, Sonnet 5.5 "far exceeds Sonnet 5's best score for less than a tenth of the cost per task."
🖼️ Side by Side: The Same Prompt, Two Models
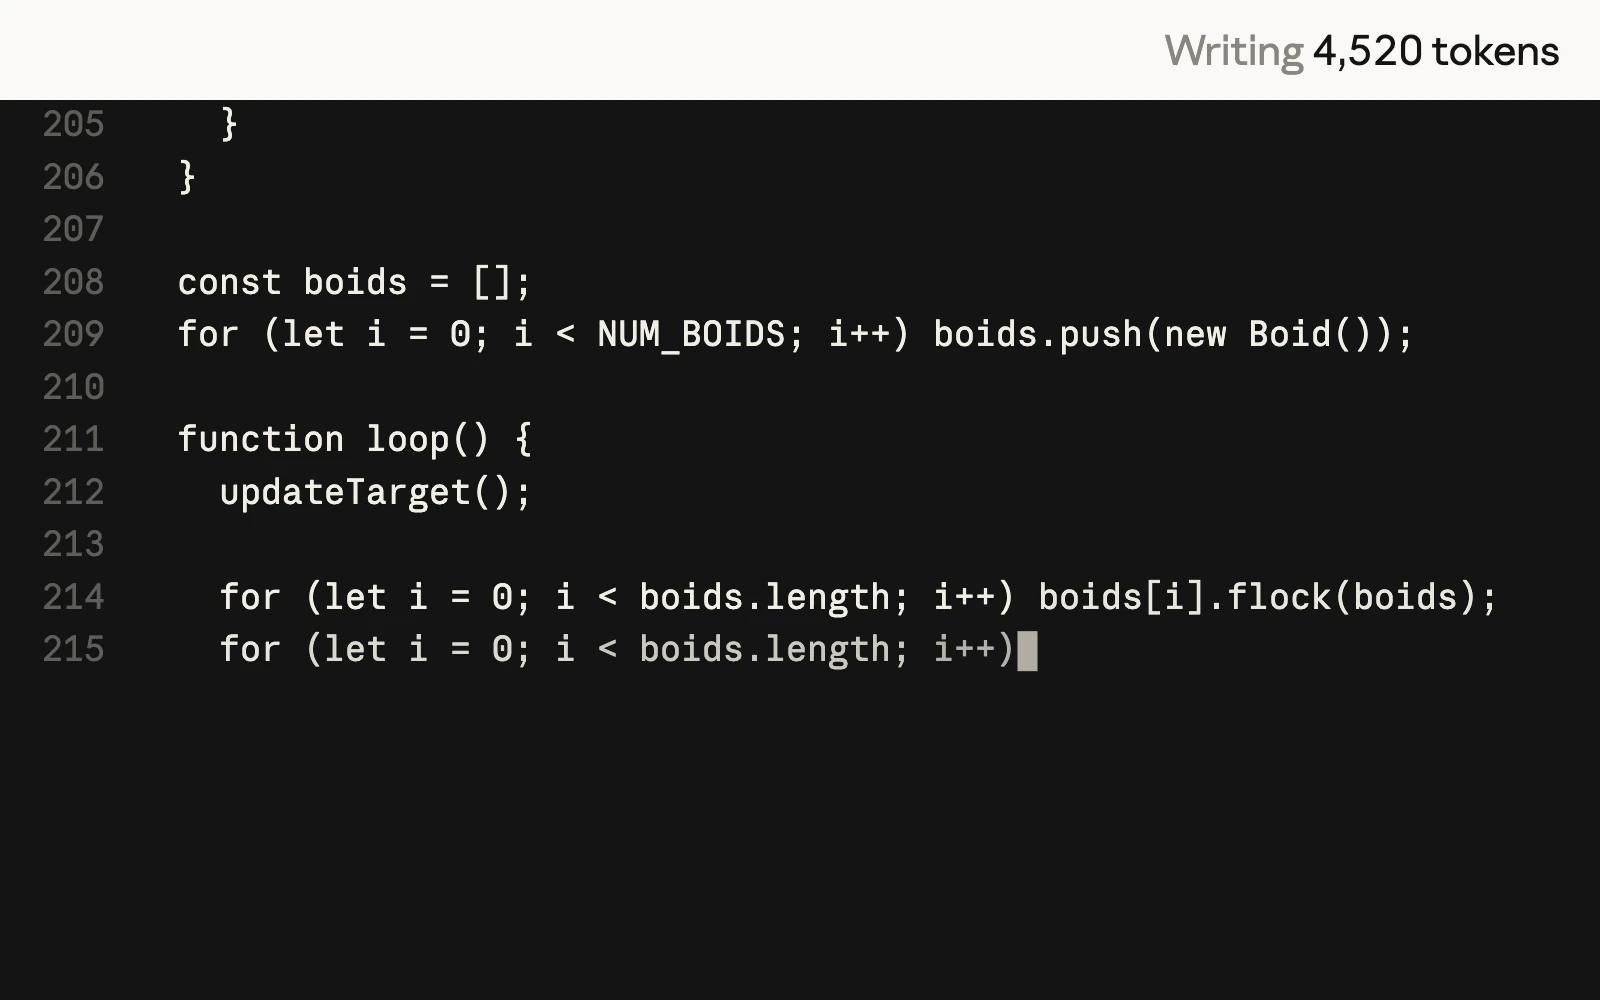
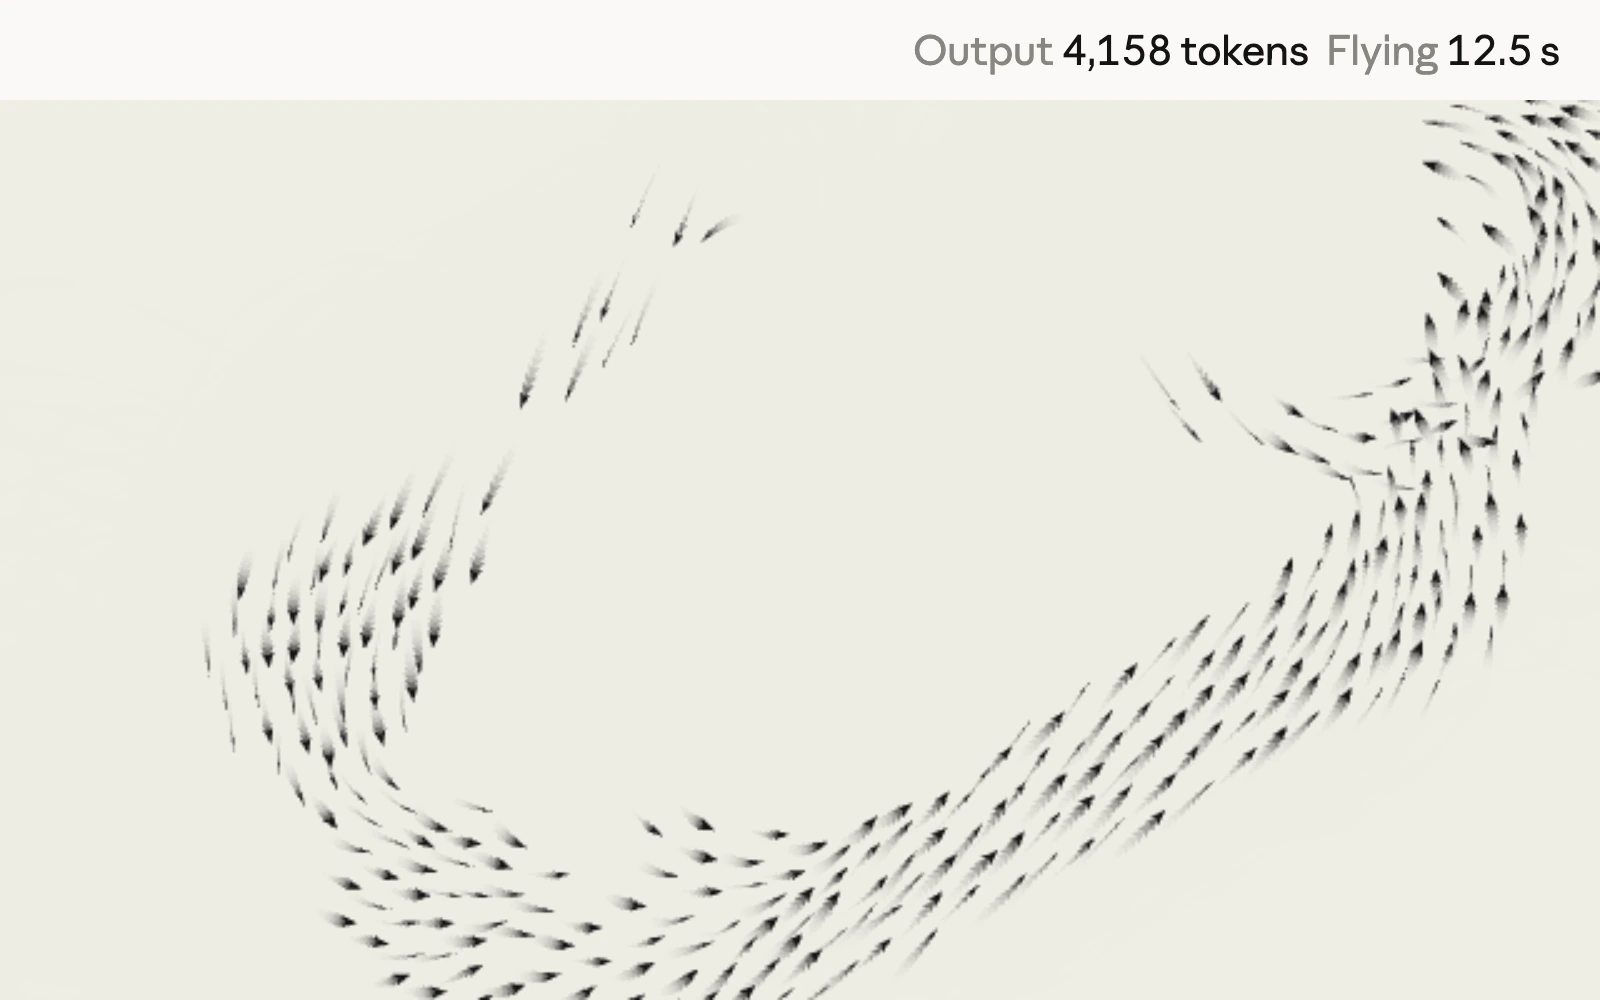
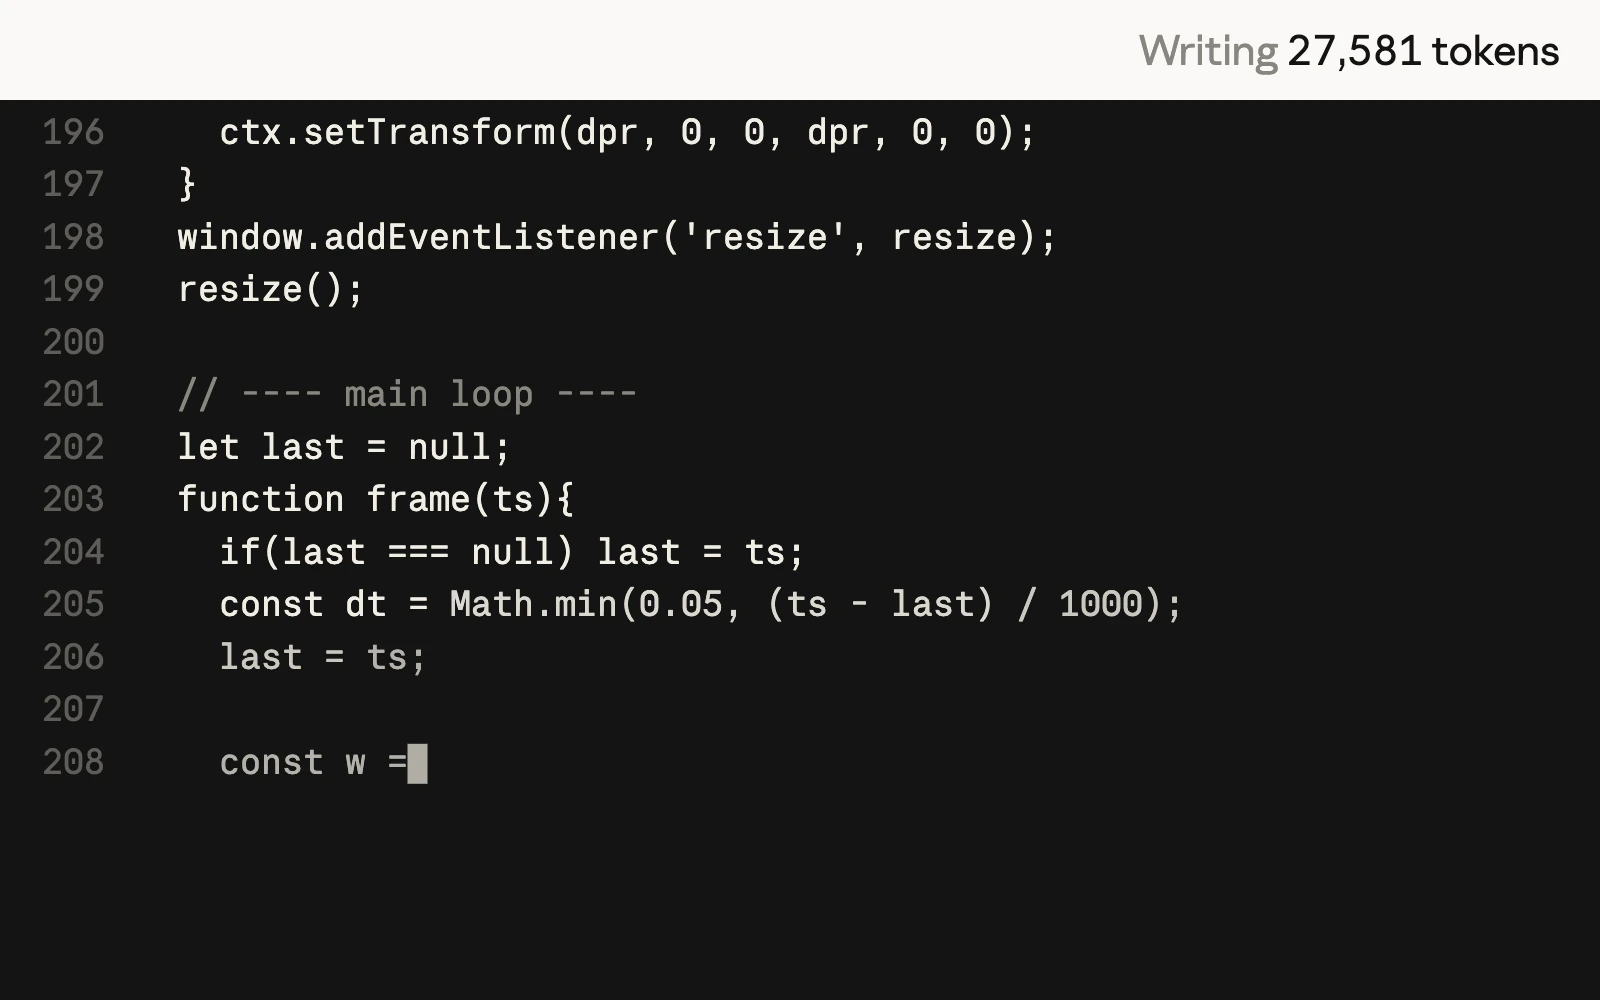
Anthropic's launch page shows the previous Sonnet and the latest model writing the same visual programs:
| Previous model | Latest model (Sonnet 5.5) |
|---|---|
 |
 |
 |
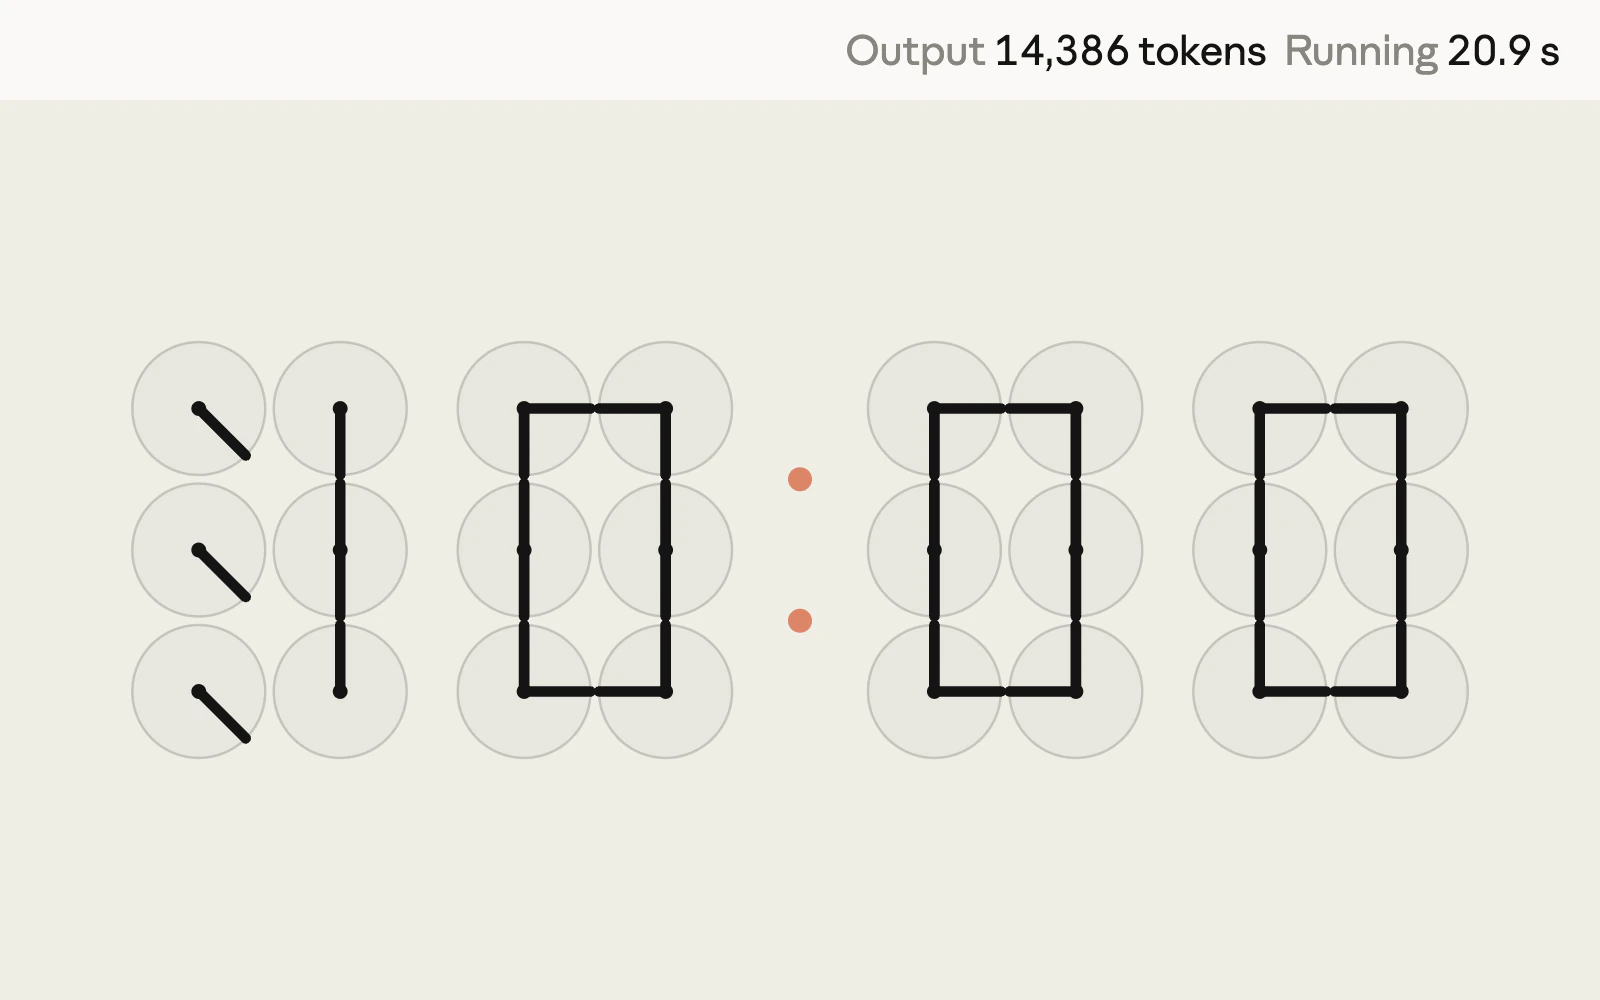 |
Starling murmuration and clock-of-clocks programs, previous model vs latest model. Source: Anthropic
🏢 What Early Customers Report
Anthropic published feedback from several early-access companies:
- ✅ Epic Games: "Claude Sonnet 5.5 cleared the same quality bar you'd expect from a higher-tier model."
- ✅ Slack: Sonnet 5.5 did better than Sonnet 5 on almost all of its offline Slackbot evals, and in fewer steps.
- ✅ Zendesk: "Tickets were processed 20% faster."
- ✅ Atlassian: Sonnet 5.5 will let teams run their Rovo Agents up to 30% faster.
🛡️ First Sonnet with Frontier-Style Safeguards
The safety changes are new for this tier. Anthropic says that Sonnet 5.5's cyber capabilities "are a large improvement over Sonnet 5's," so it is deploying the model with safeguards similar to those on Opus 5.5.
| Safeguard | What It Does |
|---|---|
| 🔐 Cyber safeguards | Similar to Opus 5.5; higher-risk cybersecurity tasks "will visibly fall back to Sonnet 5" |
| 🧬 Biology safeguards | The same set as Sonnet 5; some microbiology and virology requests may be flagged in error |
| 🧩 Reasoning-extraction classifiers | Sonnet 5.5 is "the first Sonnet model to launch with safety classifiers that prevent reasoning extraction" |
| 🔗 Expanded preserved thinking | Claude's thinking "cannot be decoupled from the account that created it" |
Anthropic also explains why its alignment review was narrower this time. Because Sonnet 5.5 "doesn't advance the frontier of our models' capabilities," the assessment focused on a targeted set of risks that apply to models at any capability level.
💭 Opus-class safeguards now apply to the mid-tier model too, so production apps on Sonnet will see the same cyber guardrails as apps on Opus.
🧑💻 What It Means for Teams and Developers
For a software consultancy, Sonnet is usually the model that runs in production: in CI pipelines, support bots and coding agents that run thousands of times a day. Sonnet 5.5 changes several practical decisions:
| Decision | What to Do Now |
|---|---|
| 🔁 Model routing | Re-test tasks you send to Opus. For terminal-heavy agentic coding, Sonnet 5.5 may match or beat Opus at half the token price. |
| ⚙️ API migration | If you run Sonnet with thinking turned off, switch to the new between_tools setting before moving to Sonnet 5.5. This is a required change. |
| 🎚️ Effort levels | Start at Medium effort, the default in the Claude apps, and raise it only for tasks that measurably benefit. |
| 🛡️ Security tooling | If your product performs security analysis, test for the visible fallback to Sonnet 5 on higher-risk cyber tasks, and plan your UX around it. |
| 📏 Measure cost per task | The price per token is unchanged, but per-task costs may drop. Re-run your cost dashboards rather than assuming the same spend. |
✅ Practical next step: Pick one high-volume workflow, such as code review, ticket triage or test generation. A/B test Sonnet 5 against Sonnet 5.5 on pass rate, latency and cost per completed task, then roll out the winner.
✨ Conclusion
Claude Sonnet 5.5 brings the main benefits of the Claude 5.5 generation to Anthropic's mid-tier model. It is faster and costs less per task, and on Terminal-Bench 4.0 it scores higher than Opus 5.5. It is also the first Sonnet to ship with frontier-style cyber safeguards and anti-distillation classifiers. For most teams, the hard question is no longer whether Sonnet is good enough. It is which workloads still need Opus.
💭 When the mid-tier model wins on agentic coding, it is time to revisit your model routing.
Tags: #Claude #ClaudeSonnet #Anthropic #AIModels #AgenticCoding #AISafety #BigMatrixSolutions
Sources:
- Introducing Claude Sonnet 5.5 — Anthropic
- Introducing Claude Opus 5.5 — Anthropic
- Anthropic releases Claude Sonnet 5.5 with the cyber limits it reserved for its best models — The Next Web
- Anthropic Releases Claude Sonnet 5.5: 70.6% on Terminal-Bench 4.0 at the Same $2/$10 Price — MarkTechPost
Media credits:
- Hero image and side-by-side program comparisons — Anthropic